Scene Parsing and Geometric Vision — Two-Stream Interactive Joint Learning Framework
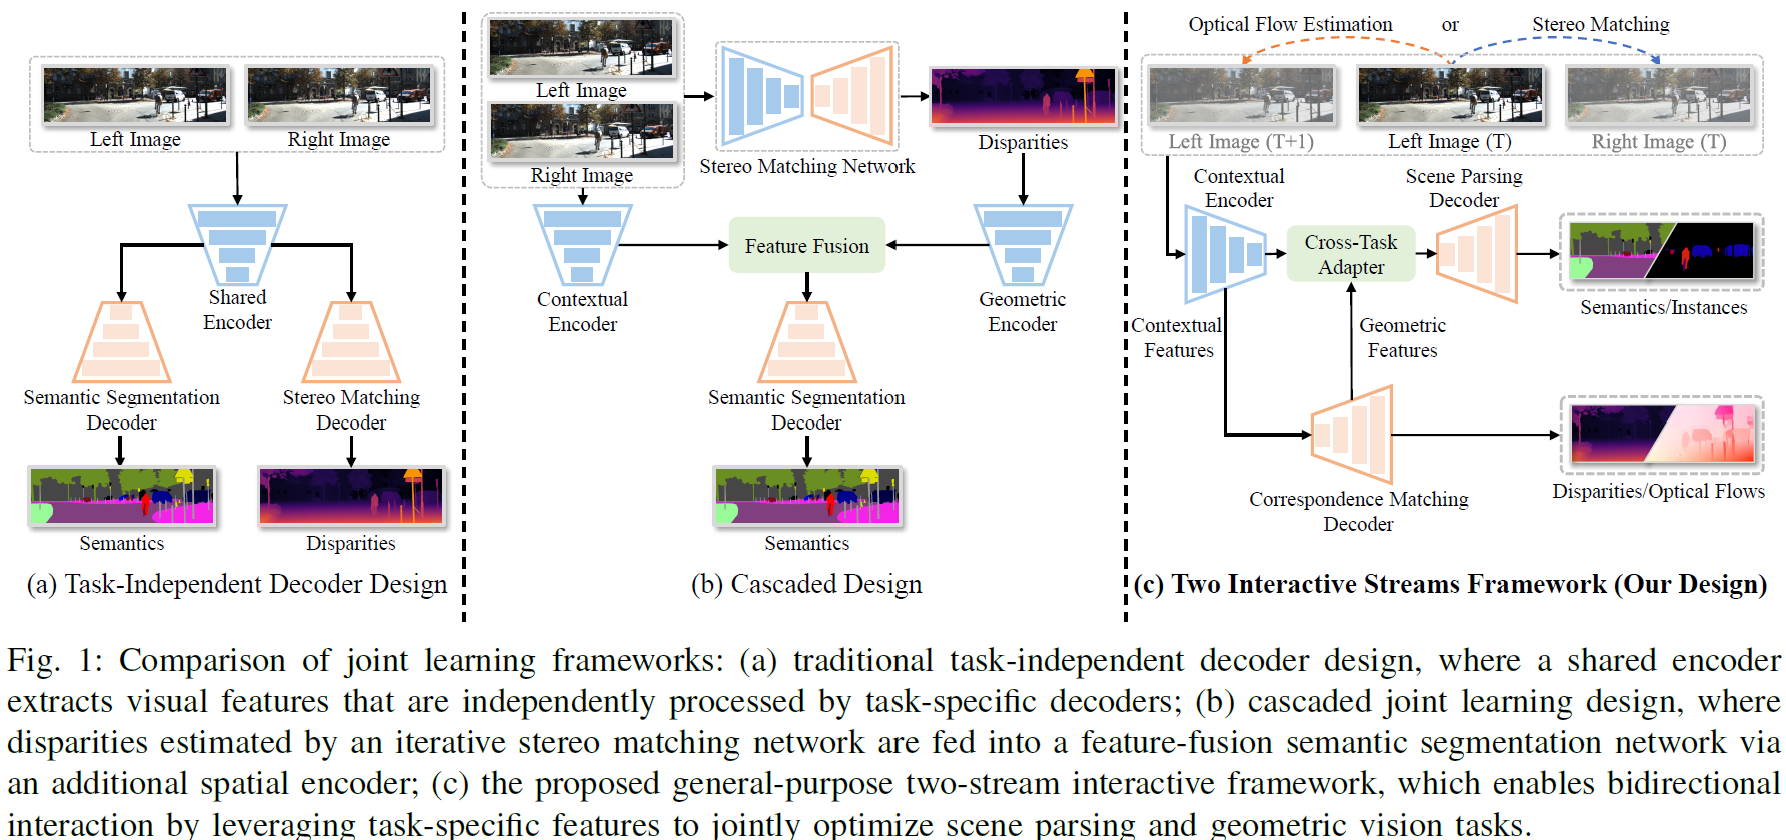
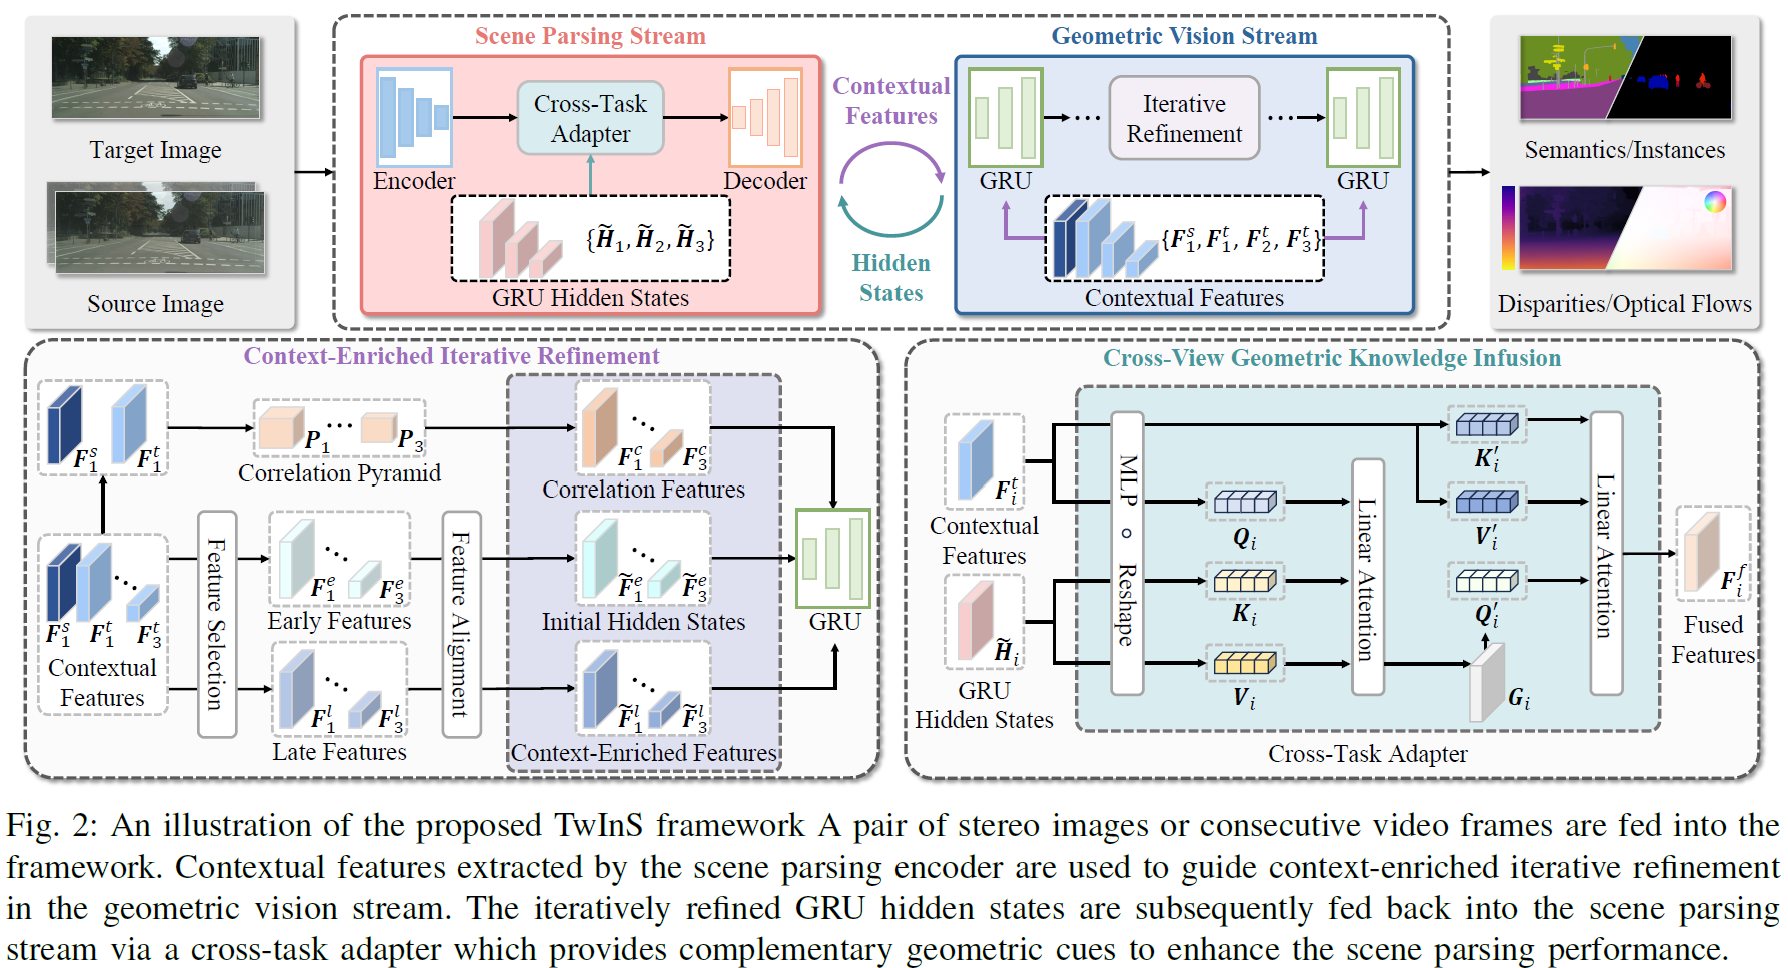
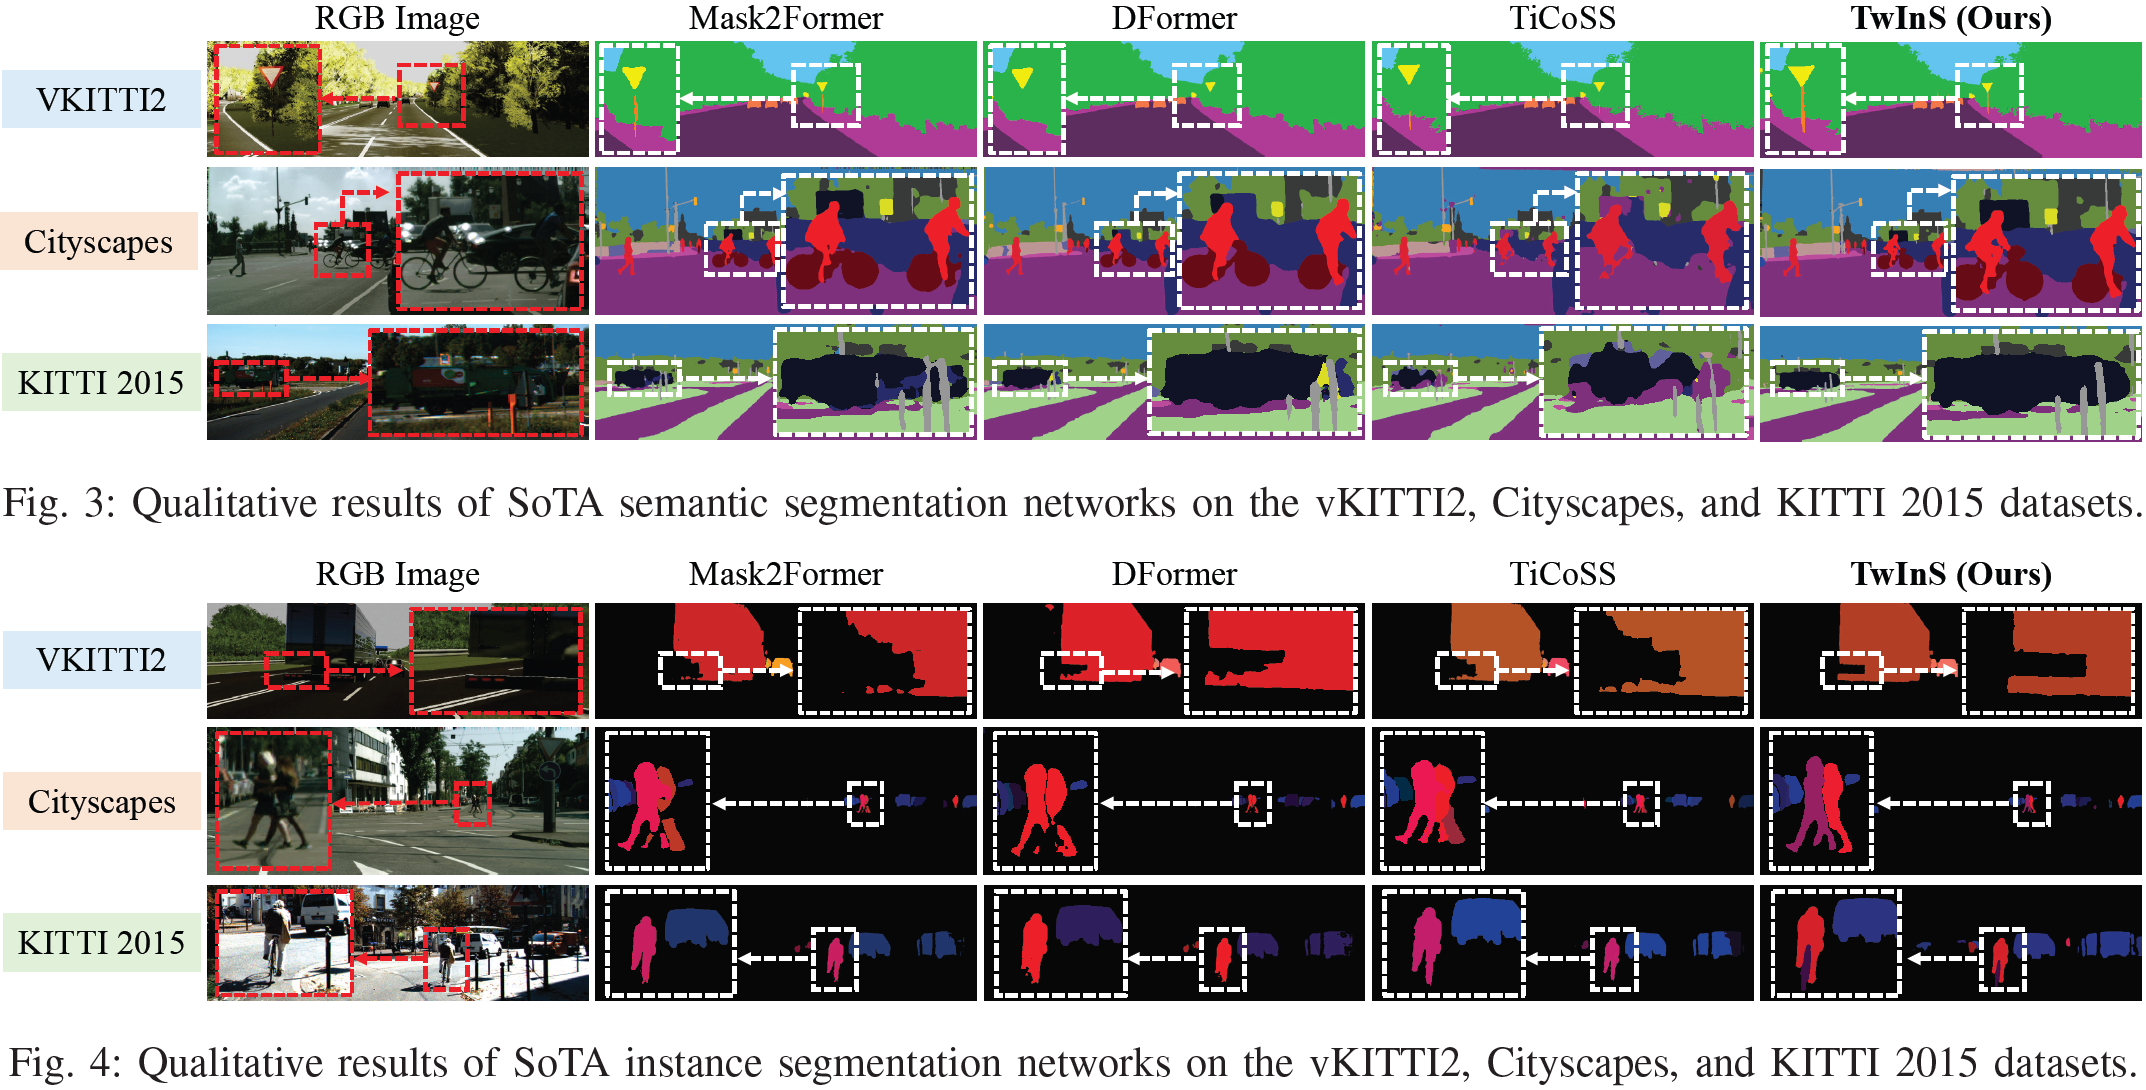
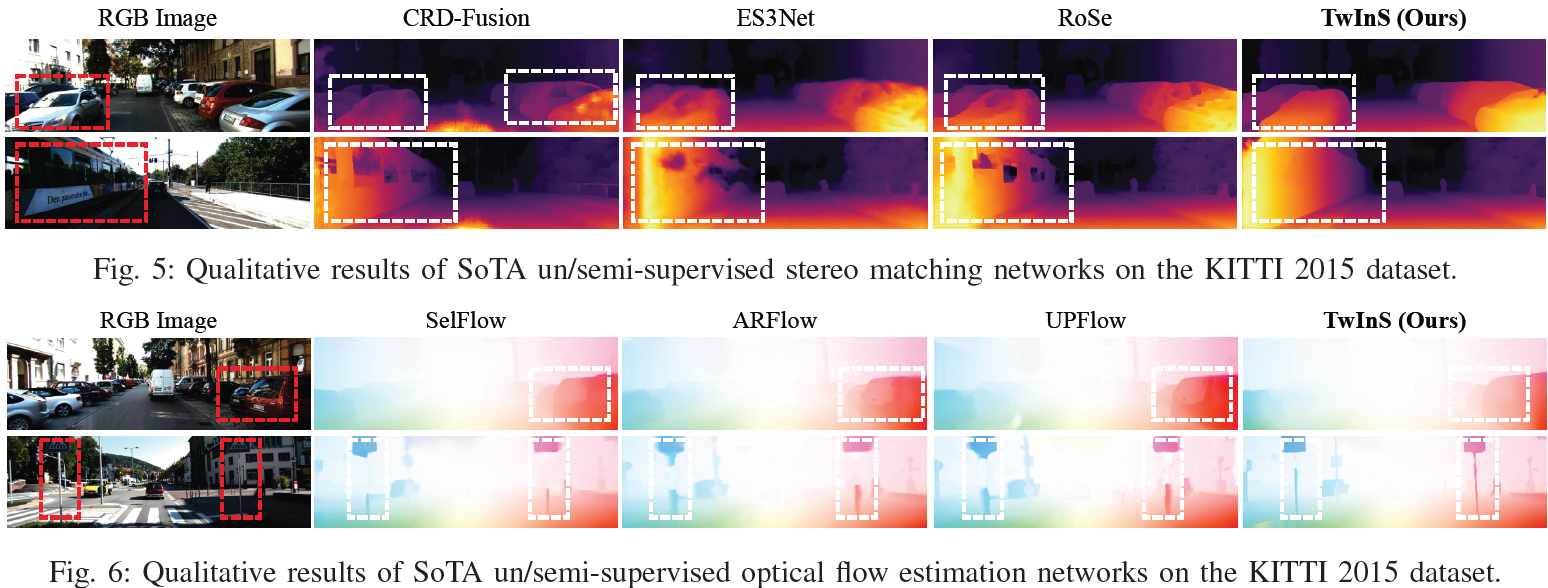
Developed a two-stream interactive joint learning framework for scene parsing and geometric vision tasks. The framework enhances segmentation performance by incorporating cross-view geometric information from the geometric vision stream, improving semantic segmentation accuracy on vKITTI2, Cityscapes, and KITTI 2015.
Single-View 3D Occupancy Prediction and Spatial Perception — ViPOcc Framework
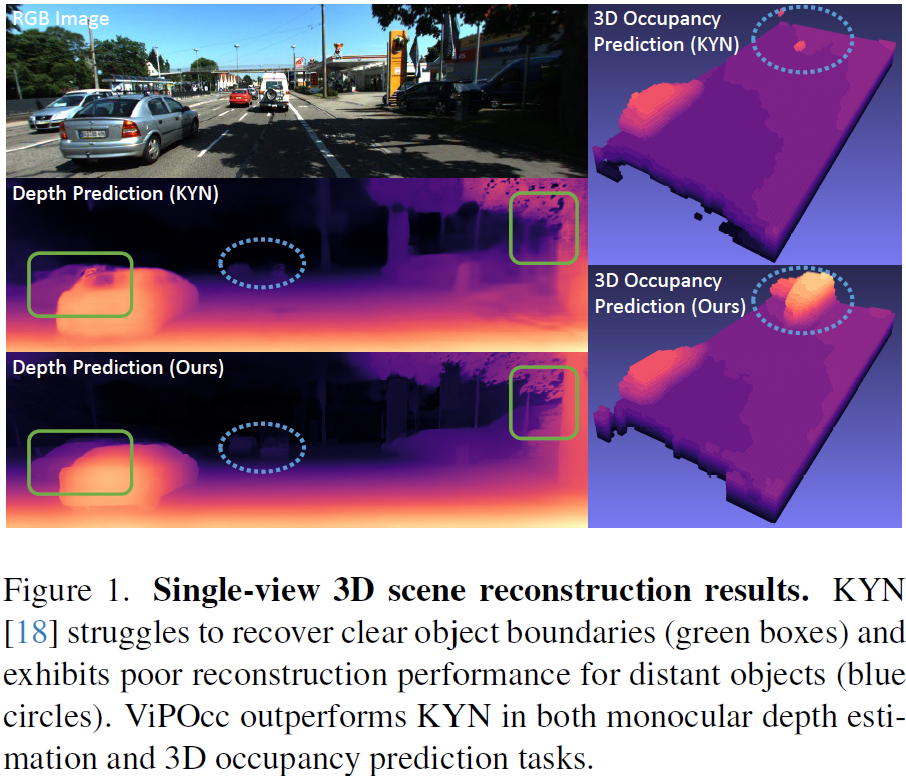
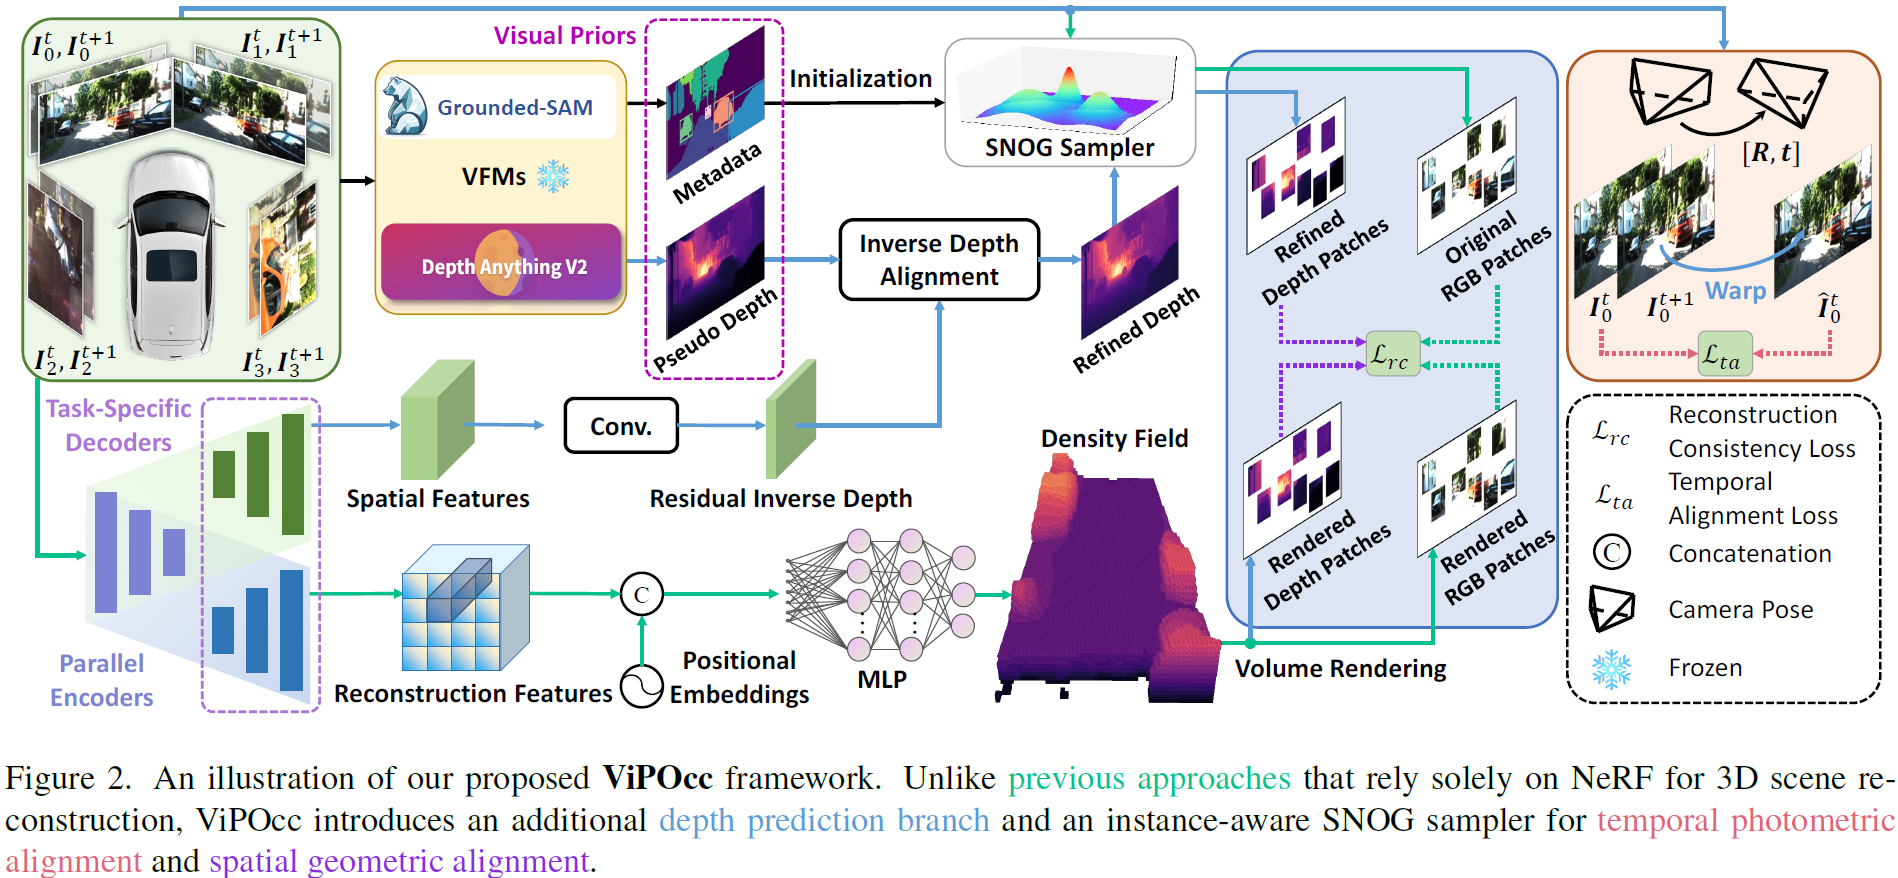
Performed monocular 3D occupancy prediction by leveraging depth and semantic-instance priors from visual foundation models, an inverse-depth alignment module, and Semantic-guided Non-overlapping Gaussian Mixture Sampling (SNOG) to improve spatial perception from RGB images.
Dynamic Robot Navigation — Optimization of 2D LiDAR-Based Pedestrian Detection
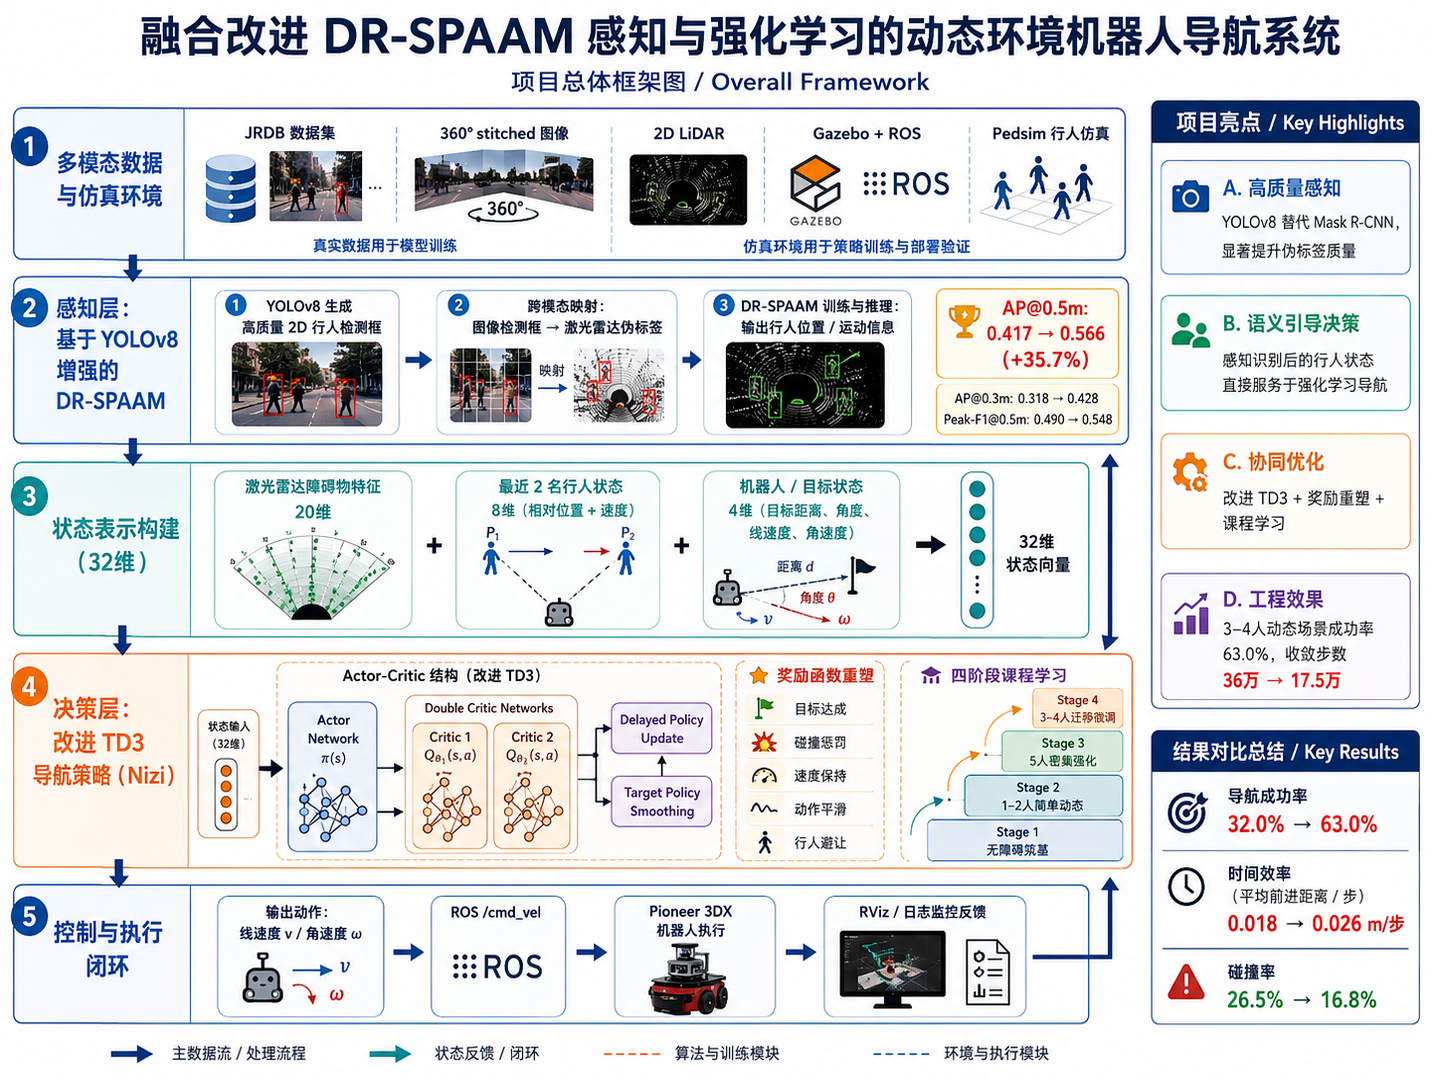
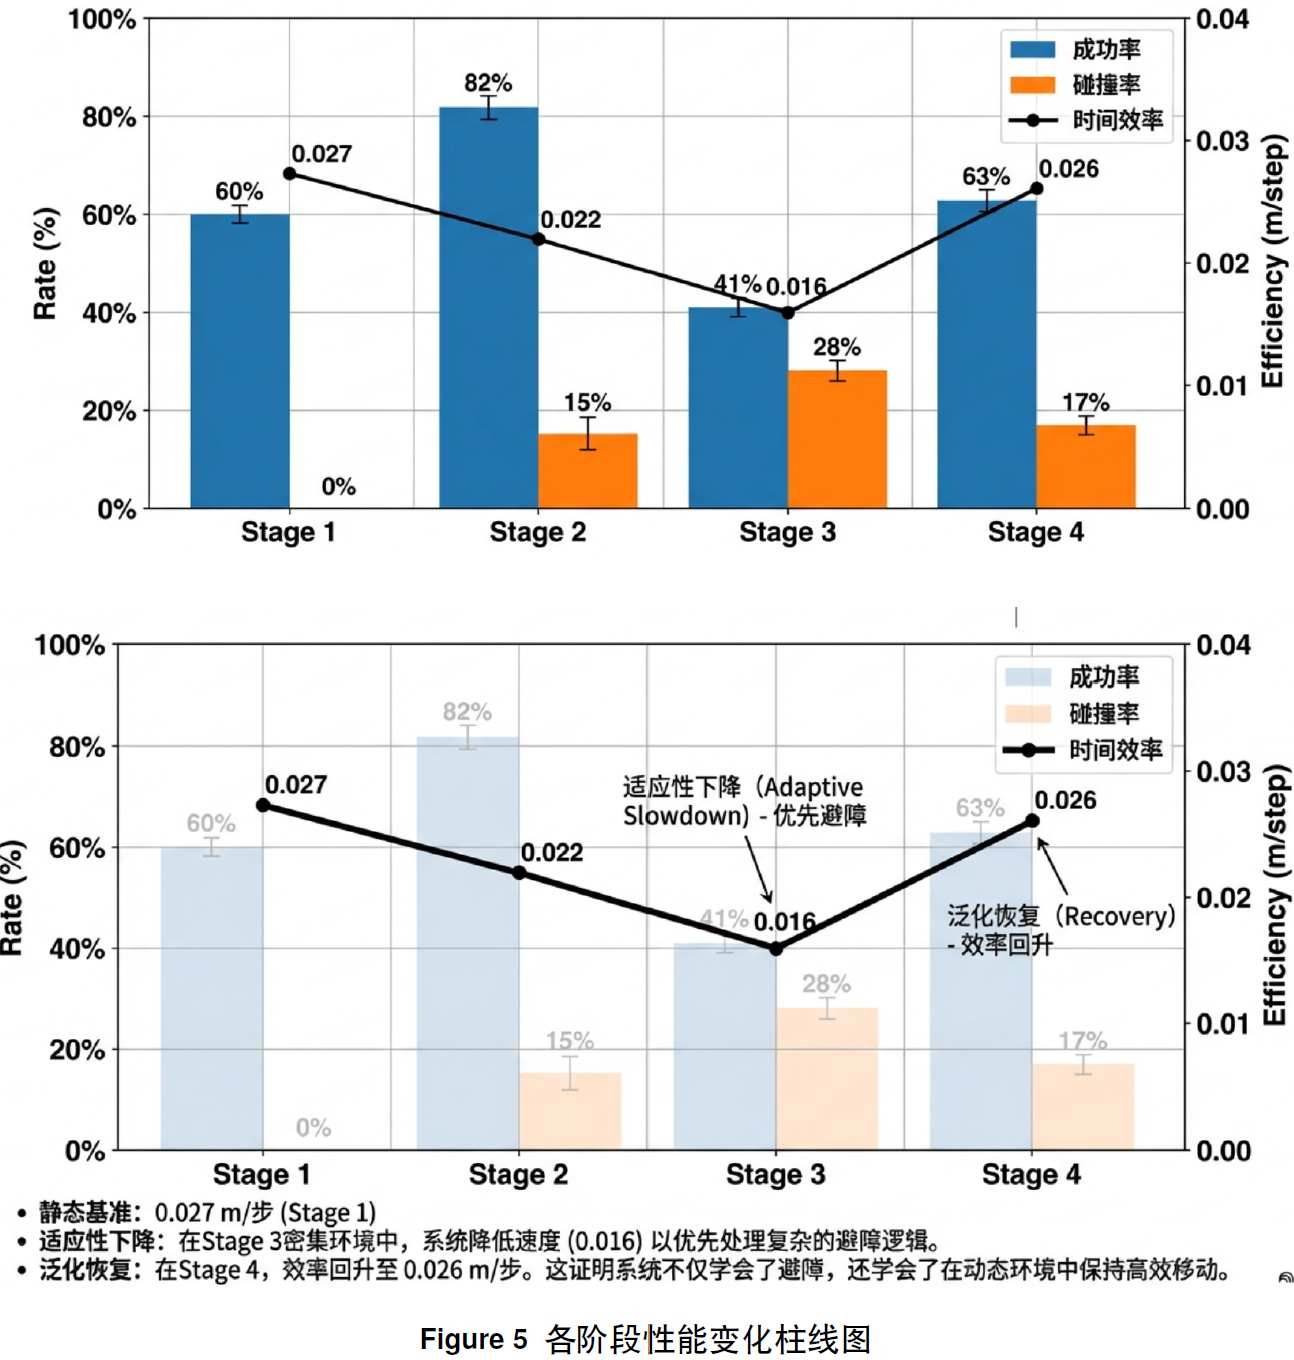
Developed a dynamic navigation system integrating perception and decision-making for mobile robot navigation in dynamic environments. The perception module was optimized based on DR-SPAAM, while the decision-making module adopted TD3 reinforcement learning with a four-stage curriculum learning strategy.
LLM Trustworthiness and Safety — Library Recommendation and Code Migration Quality Evaluation
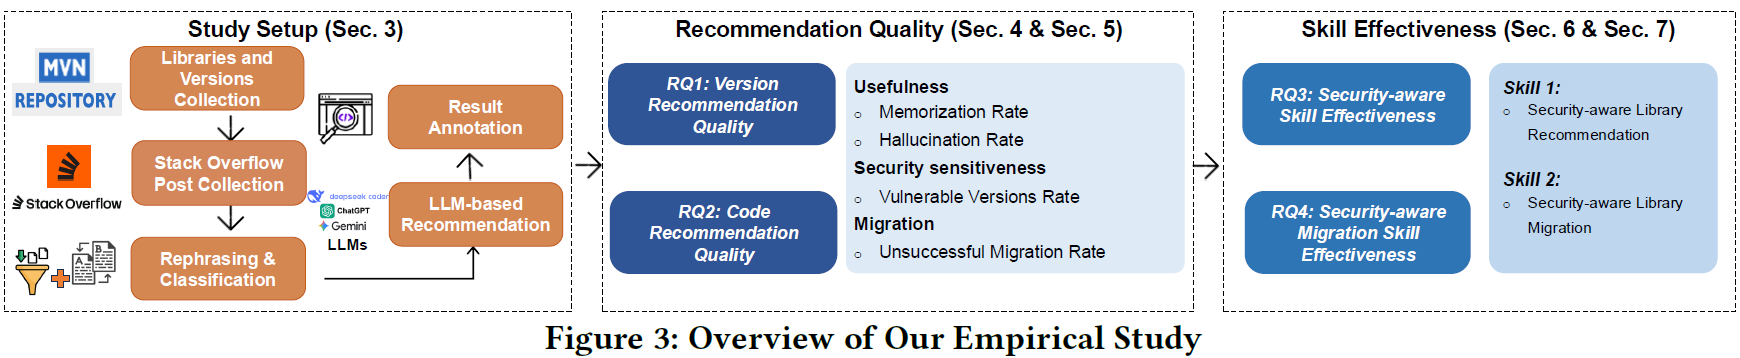
Conducted an empirical study on the reliability and safety of LLM-based Java third-party library recommendation and usage generation. The study built an evaluation pipeline based on Stack Overflow posts, Maven metadata, and vulnerability data, analyzing version recommendation, code usage generation, secure version migration, and security-aware Skill prompting. It further examined how security-aware prompts improve secure version statements, dependency-version consistency, and API compatibility.
Vision-and-Language Navigation — Literature Review and Exploratory Study
Conducted a systematic review of recent Vision-and-Language Navigation studies. Summarized key challenges in long-horizon navigation, including cross-modal instruction grounding, memory compression, streaming decision-making, and closed-loop error correction, with a focus on VLM-as-Brain paradigms.
- Vision-and-Language Navigation
- Embodied AI
- Cross-modal Grounding
- Long-horizon Navigation
- Closed-loop Correction